Qwen-Image-2.1-mflux-q4 ↗
apache-2.0
Repository updated: 2026-09-26Choose what you want to do. Explore quality, hardware estimates and sources before deciding what to run.
| # | Model | LiveBench / 100 | Memory · Q4 estimate | Weight license |
|---|---|---|---|---|
| 1 | Smaug MiniAbacus AI | 76.9 | ~29 GB | Apache 2.0 ↗ |
| 2 | Qwen3.8 27BAlibaba | 75.3 | ~29 GB | Apache 2.0 ↗ |
| 3 | Qwen3.6 27BAlibaba | 64.0 | ~29 GB | Apache 2.0 ↗ |
LiveBench 2026-06-25 ↗ · Selected task: Overall · Scores collected: 2026-09-26. Positions cover only evaluated models within the selected memory budget. This LiveBench score is not the Artificial Analysis Intelligence Index, and the two scales are not directly comparable.
Speed depends on the computer, runtime and quantization. Check tokens/s and time to first token with the measured configuration.
Checking the latest saved data…
LOCAL AI WIZARD
Start with the task. Find the right model for you.
These entries update with the catalog, even without a benchmark. Repository changes are not necessarily new model releases.
apache-2.0
Repository updated: 2026-09-26apache-2.0
Repository updated: 2026-09-25Check license at source
Repository updated: 2026-09-25mit
Repository updated: 2026-09-25openmdw-1.1
Repository updated: 2026-09-25mit
Repository updated: 2026-09-2451 open-weight entries in the Artificial Analysis snapshot checked 2026-09-22, with deeper technical review where primary evidence is available.
The complete ranked set comes from one Artificial Analysis arena snapshot per modality, so ranks and Elo scores are comparable only inside that modality. API variants can share the same public checkpoint.
A reviewed badge means license, components or hardware were checked against primary sources. Benchmark-only entries remain visible for coverage, with unknown facts clearly marked instead of inferred.
51 models · 51 ranked · 9 technical profiles reviewed · benchmark snapshot ↗ 2026-09-22
19 of 51 visible models have a documented memory path. Open the rankings for every model.
| Field |
|---|
| Task |
| Parameters |
| Repository size |
| Components |
| Hardware |
| License |
Choose models to compare.
7 open-weight entries in the Artificial Analysis snapshot checked 2026-09-22, with deeper technical review where primary evidence is available.
The complete ranked set comes from one Artificial Analysis arena snapshot per modality, so ranks and Elo scores are comparable only inside that modality. API variants can share the same public checkpoint.
A reviewed badge means license, components or hardware were checked against primary sources. Benchmark-only entries remain visible for coverage, with unknown facts clearly marked instead of inferred.
13 models · 7 ranked · 6 technical profiles reviewed · benchmark snapshot ↗ 2026-09-22
2 of 13 visible models have a documented memory path. Open the rankings for every model.
| Field |
|---|
| Task |
| Parameters |
| Repository size |
| Components |
| Hardware |
| License |
Choose models to compare.
16 open-weight entries in the Artificial Analysis snapshot checked 2026-09-22, with deeper technical review where primary evidence is available.
The complete ranked set comes from one Artificial Analysis arena snapshot per modality, so ranks and Elo scores are comparable only inside that modality. API variants can share the same public checkpoint.
A reviewed badge means license, components or hardware were checked against primary sources. Benchmark-only entries remain visible for coverage, with unknown facts clearly marked instead of inferred.
19 models · 16 ranked · 3 technical profiles reviewed · benchmark snapshot ↗ 2026-09-22
8 of 19 visible models have a documented memory path. Open the rankings for every model.
| Field |
|---|
| Task |
| Parameters |
| Repository size |
| Components |
| Hardware |
| License |
Choose models to compare.
Choose a device and memory capacity. Each profile brings together specifications, candidate models, settings and available measurements.
There was no Mac mini M3. Compare generations, then choose the real memory configuration.
Choose chip and memory. Each option opens its profile and model estimates for that capacity.
Choose chip and memory. Each option opens its profile and model estimates for that capacity.

Choose chip and memory. Each option opens its profile and model estimates for that capacity.
Choose chip and memory. Each option opens its profile and model estimates for that capacity.
Card VRAM; system RAM and runtime support are separate. Check the SKU when 8 and 16 GB versions exist.
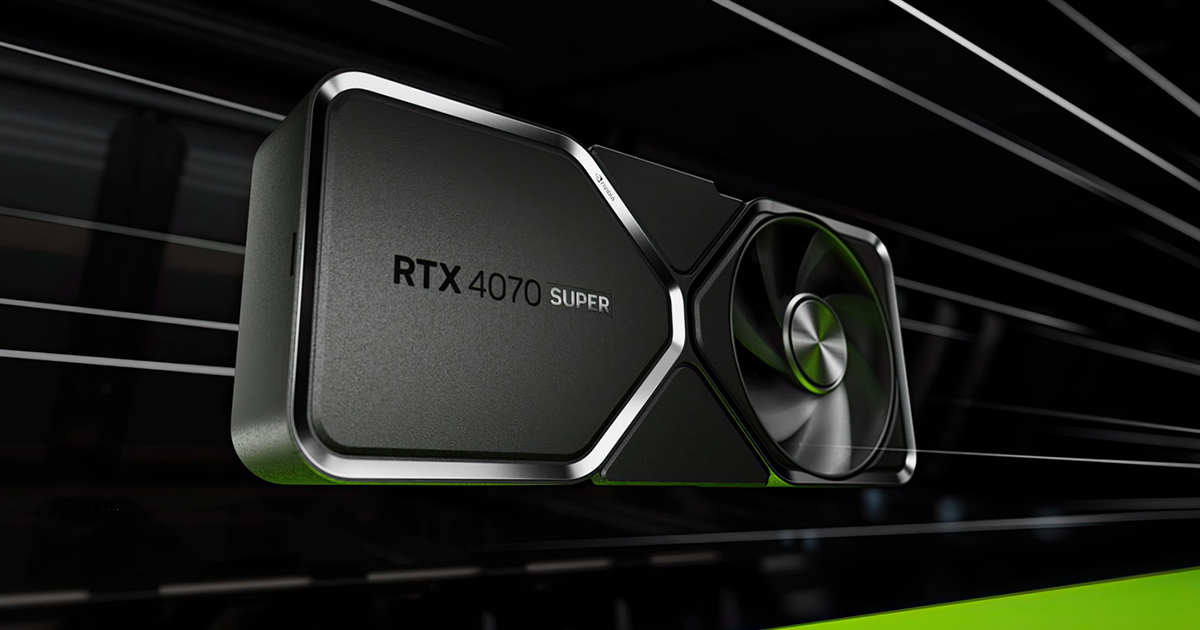
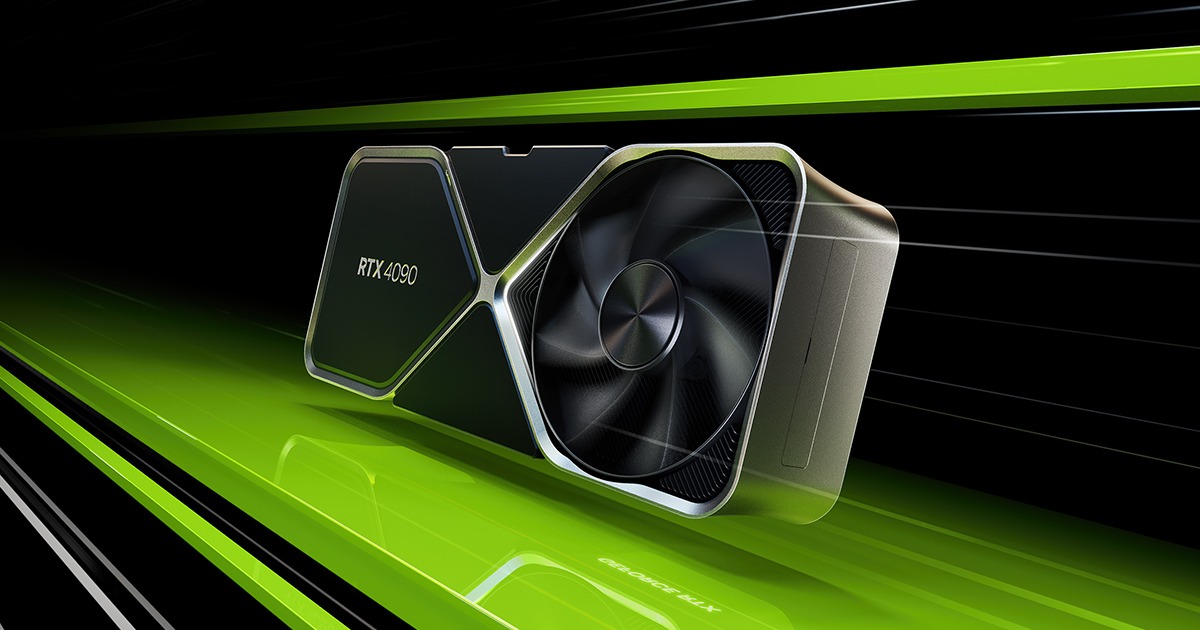
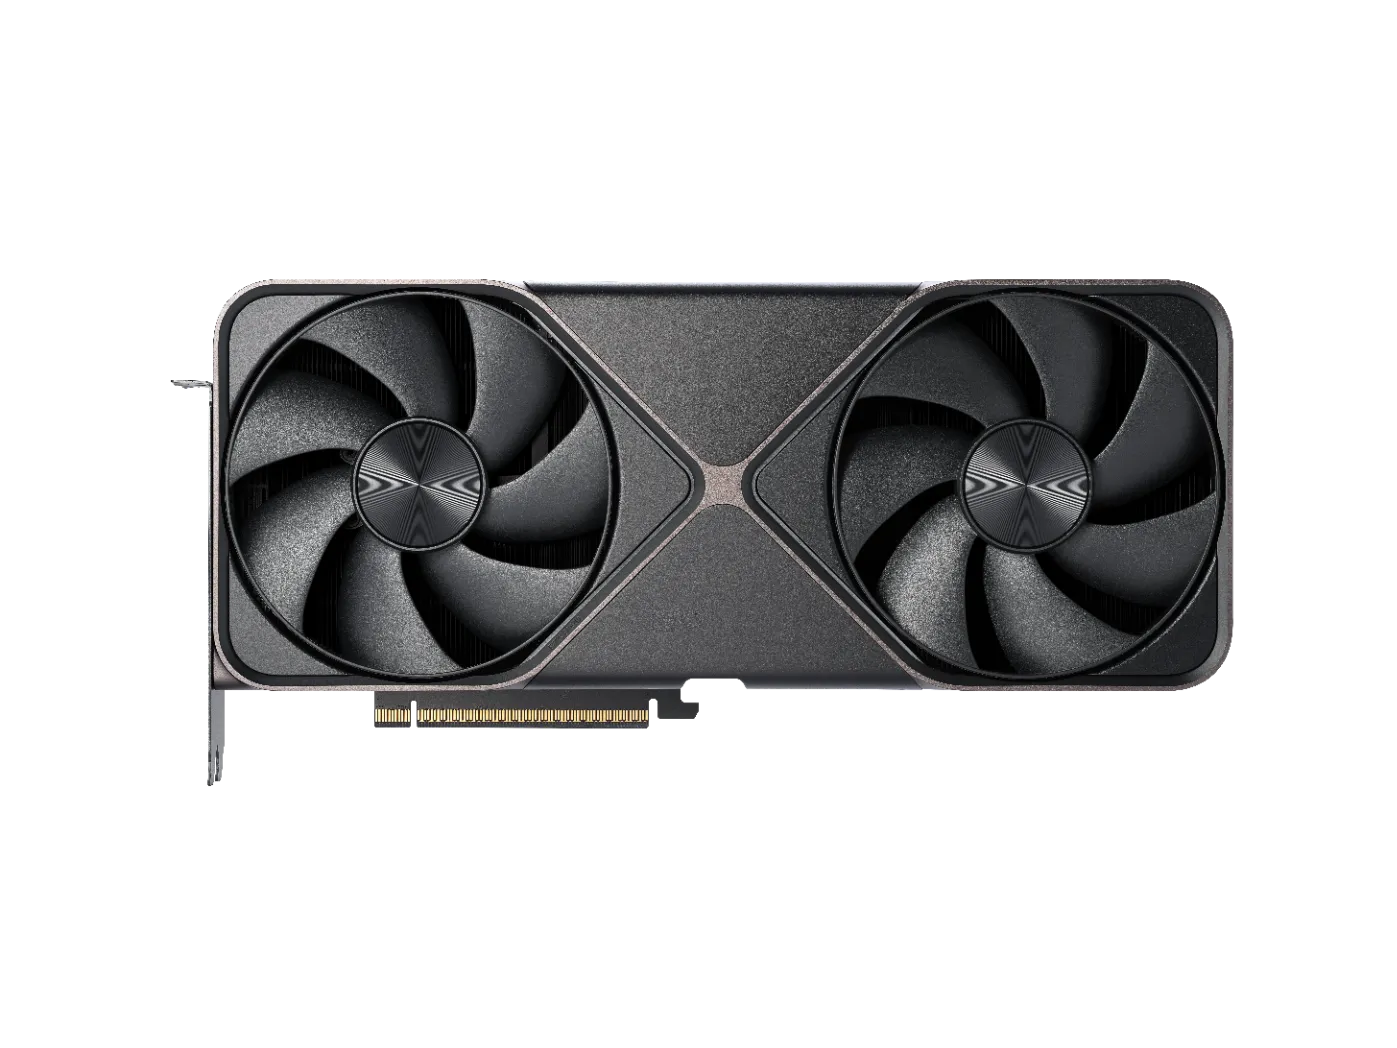
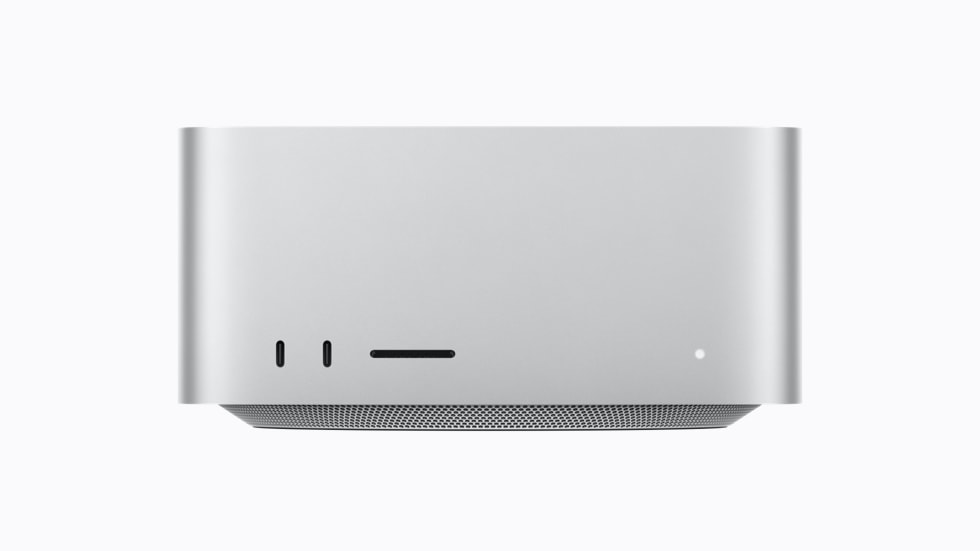
Choose chip and memory. Each option opens its profile and model estimates for that capacity.
12 checkpoint profiles, 22 hardware configurations and 3 task comparisons. Each page keeps its source, date and limits visible.
1420 source repositories in the catalog.
The overall score is the equally weighted mean of seven category means (0–100). All scores use one release. This is not the Artificial Analysis Intelligence Index; the two scales must not be mixed.
CSV ↗ · Categories ↗ · LiveBench ↗ · Data reuse policy ↗Planning formula: total parameters × 0.625 bytes, plus 20% working allowance and 8 GB reserve, rounded up in decimal GB. This is a heuristic, not a measured minimum or guarantee. Quantization, context, KV cache, vision components, runtime and offloading change requirements. MoE uses total parameters, not only active ones.
Qwen counts refer to language parameters; GLM-5.3 and DeepSeek V4 use repository tensor totals; GLM-5.3 Flash uses the manufacturer’s 320B specification. Architectures without a reviewed estimate remain outside the memory axis.
LiveBench evaluates the named model and reasoning effort. Its score is not a measurement of the local Q4 variant. Hardware links are official destinations without affiliate tracking. Stock, exact configuration and regional availability can change.
The deployed product checks scores, approved official model organizations, US prices and stock daily, and hardware specifications weekly. Due visits can also refresh safely. D1 preserves the last valid snapshot. Incompatible methodology is quarantined; unavailable sources never erase valid data. New models remain pending benchmark or insufficient data until official facts exist.